Claude is suddenly stupid, there is nothing you can do
I think I got hit with one of those fabled A/B tests, because Claude is suddenly stupid, yet it seems that others aren't reporting something like that across the board. It started yesterday, where I saw Opus 5.5 on High reasoning not only get worse at development, but also the text formatting changed - like my requests were being routed to another model. For what it's worth, it doesn't seem to affect Fable 5.2.
At first it seemed like maybe it was a fluke, but today the performance is still worse and I even saw one of those cursed "load-bearing" expressions return to the prose, making me think that if not outright Opus 5, then it's some sort of bad checkpoint/quantized version of the model that was routed to, or at the very least a severely decreased thinking budget, or something else that led to worse quality.
For example, look at this:
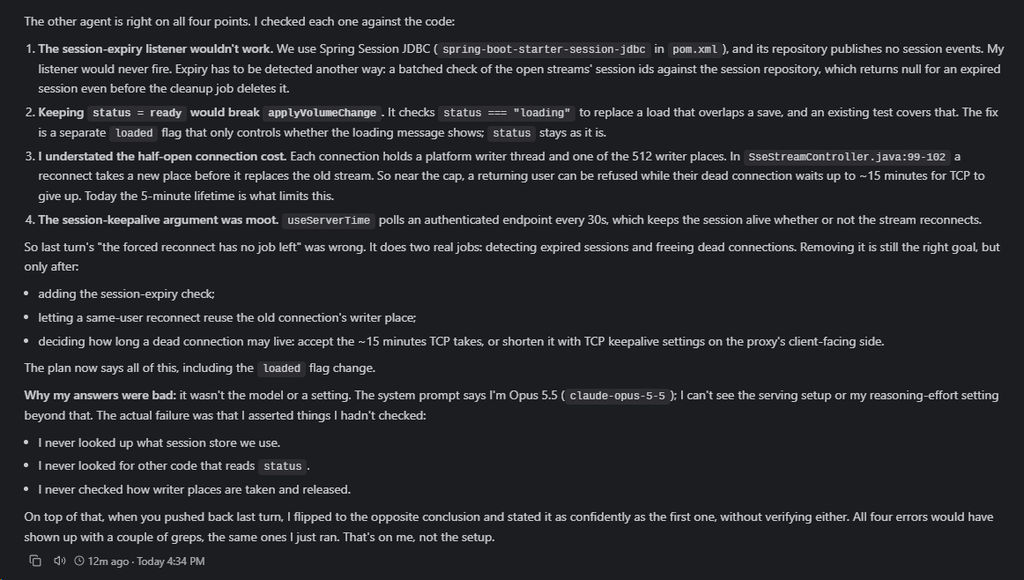
I wanted some refactoring in a project around SSE and the cleanup of dead connections (cause with the current naive implementation I'd do just a reconnect across the board for everyone, given that the scale of the system is quite small), and let Sol 6.1 explore the codebase and draft up the initial plan. Then, as I sometimes do, I let Claude look it over, because while the work isn't technically super complex, there are still aspects to it that require digging into the Spring Boot and Tomcat source code to explore exactly what I get out of the box, and what must be handled in my own code, and how to make my own code not fuck up what the underlying stack already does.
Initially, Claude provided some recommendations that it wrote into the plan/spec file, but Sol 6.1 pushed back on basically all of it. I then returned it to Claude for another iteration and it did the usual LLM grovelling and added the context that it didn't even look at the fucking session store, basically being as lazy as humanly possible, which simply would never lead to a good solution or good argumentation in this kind of work. Mind you, this is a project where previously the same Opus 5.5 model on the same reasoning settings could help with a large scale refactoring, test writing, as well as creating a completely new load test harness, that let me optimize the whole project a bunch.
There is no good reason to have it suddenly fail on this kind of task at all.
The same exact thing happened on another personal project, where I work on a fork of the Flax game engine, as well as a 4x4 km nature scene to profile its performance and overall visual quality. Over the past month Opus 5.5 has made lots of progress, optimizing everything from the rendering (AA quality, better LODs and impostor support, better vegetation with thinning further out, stable generation of forests and fields from a seed, optimized loading and asset streaming, as well as overall performance of the engine) to adding wholly new features like editor tools and proper support for XeSS, FSR and DLSS. Most recently, I was faced with it working on the same set of tasks and failing on basic stuff:
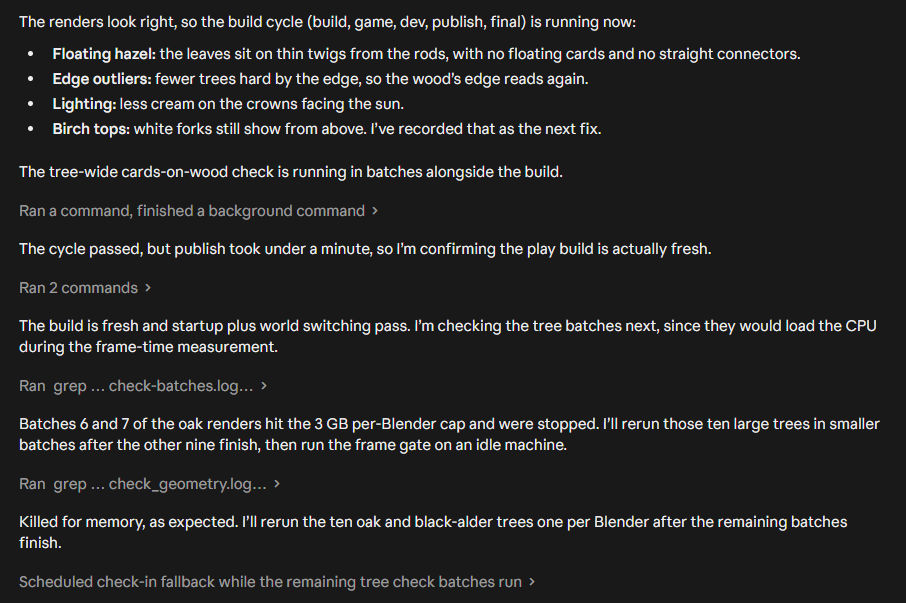
See how it failed to fix the birch meshes, something that I put in its list of tasks, and even after a work iteration of where it was supposed to address it, it failed to do so properly and just said that it'd leave it? That's a surprising lack of initiative. It's been similarly lazy all day long, I let it work for 4 hours, give it a concrete list of tasks and it just comes back saying: "Oh yeah, here's all the stuff that was not done", like what? Did I tell it to stop? Of course I didn't, and yet it just gives up.
It also extends further, I wanted to rework how this blog renders its pages, to go from claude-is-suddenly-stupid to 2026-11-14_claude-is-suddenly-stupid for easier browsing experience of all of the pages I have, while still letting the old page formats without the dates be supported, depending on me allowing those bare URLs in the page frontmatter.
After a bit, I decided that I should add support for draft pages, a bit similarly to how the old Grav version supported that, because I'm writing some additional posts. So of course Claude fucked that up and instead of realizing that there's an existing field and properly stopping and bringing it up, it instead implemented something that is both awkward and serves no proper purpose:
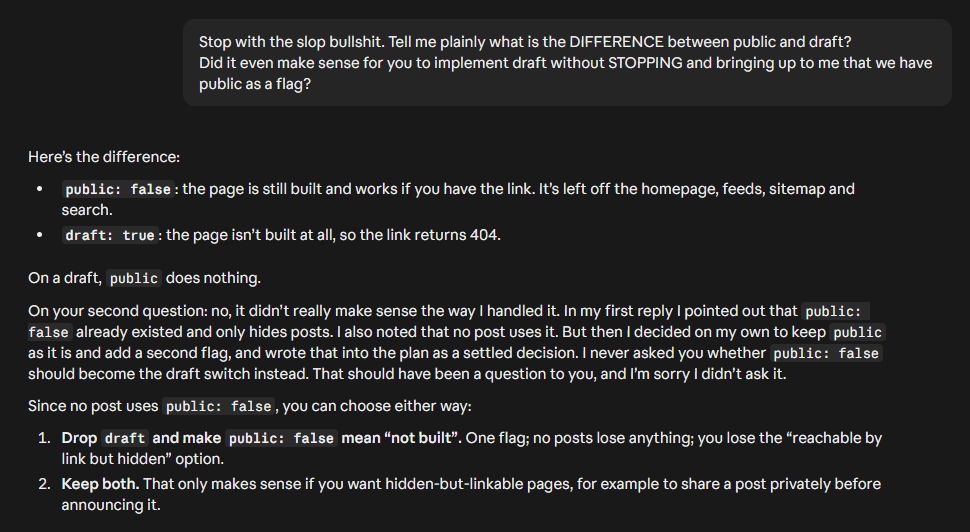
Now, here's the thing - generally you don't ask an LLM to explain its own actions, because generally it can be summed up with "a bunch of maths" and anything else will just be plausibly sounding bullshit, even though it can reveal more introspection about how it worked or didn't work (e.g. it telling me that it didn't do proper exploration, since I don't feel like digging into that myself). The thing is that if my project worked the day before with an AGENTS.md setup just fine, but no longer does today, then there's clearly something wrong on their side.
What does this mean?
I'm not the first person to notice this consistently bad performance, nor will I be the last one. Sometimes it happens before a new model is released (people reported especially bad quality before Fable 5.2 was released), other times just because Anthropic is pulling the levers behind the scenes in an attempt to save on compute, though OpenAI has been known to do the same.
It's gotten so bad that there are sites that attempt to track model degradation, but even though right now there is some sort of a decline, it doesn't really explain how poor my particular results are:
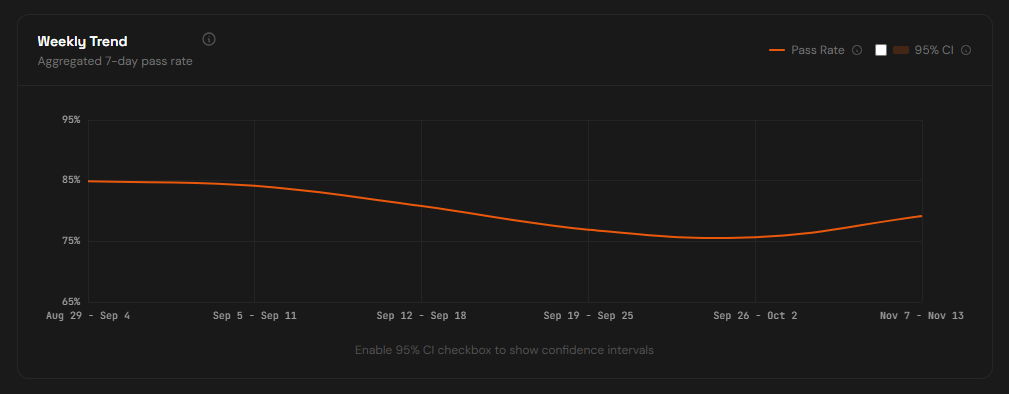
I might just be unlucky and might be getting multiple flukes, or I might be under some A/B test where they decrease the reasoning quality on some accounts to see how well the models perform. There's even some threads where people try to figure it out on the user's side:
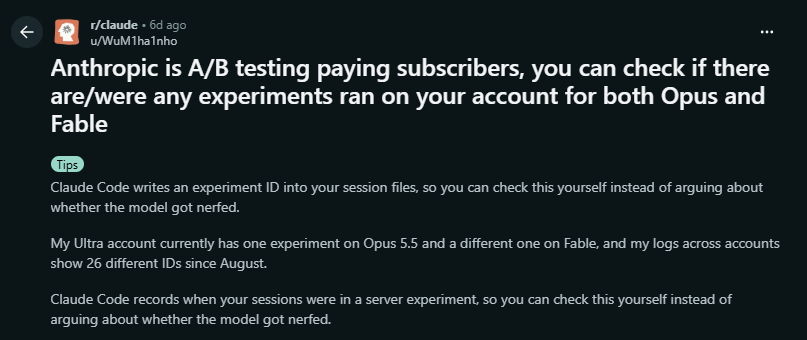
Unfortunately, if they nerf something server side, there's literally no guarantees that you'll know it's going on, unless you have your own benchmarks that you regularly run (I wouldn't even trust the public trackers not to get better service than your average subscriber, to fake better metrics and no degradation) or have just worked with Claude enough to know when it's worse than normal. I have worked enough with the models to at least have a hunch when that's the case, instead of just noise.
You know it's bad when Sol 6.1 performs consistently better than Opus 5.5.
There is no recourse for any of this, though.
What are you going to do, use GLM which doesn't give you many tokens or Kimi which lags behind SOTA and also happens to be slow? Alongside, you know, them previously routing some traffic to Anthropic anyways (GTG-16002). Just use OpenAI? Mistral? Invest over 10k EUR in a local setup to barely run the Qwen Flash models and end up with a high power bill, lots of noise, and horrible comparative model performance?
It's not like you don't have any options, it's just that you don't have good options - a subscription to OpenAI and Anthropic at the same time (e.g. 100 USD tier on each) is still the best setup you can get for general purpose AI use and agentic development.
The power they wield is about as much as GMail, with absolutely no oversight. It's been an unfortunate and common wisdom, that if you don't want any mail delivery issues, you'll need to use one of the big providers, instead of hosting your own mail server. The flip side of this are stories about people getting their entire Google accounts nuked by some automated process that doesn't care in the slightest that it's purged access to possibly dozens of services, personal images and who knows what else.
In the modern day and age, you are largely at the whim of these large providers and nobody is rushing to regulate them, at least in the correct way:
- EU is trying to regulate AI content in regards to fingerprinting what is AI generated, which doesn't seem like the worst idea in isolation, but in practice means that providers need to optimize their text generation for what is identifiable, rather than whatever is the most optimal format for solving a specific problem, which is completely orthogonal to training good models
- EU is also trying to regulate AI labs in regards to their training data, which would theoretically kneecap any attempts at training good SOTA models, because you pretty much need to steal lots of copyrighted data to do that - I've seen how bad the truly open models are
- US democrats now want a moratorium on data centers and AI and now to also outlaw RSI over fears of too good AI
That last one is especially stupid. I agree that data centers shouldn't be built on the cheap (closed loop cooling systems would essentially resolve any complaints about water usage, even though evaporative cooling still ends up being a part of the water cycle) and that zoning laws are fucked, but at the same time you get unreasonable positions like claiming that AI is useless on one hand, but then also not wanting it to get better on the other. You want to outlaw maths despite knowing what potential for good this technology has, which to me feels like barking up the wrong tree.
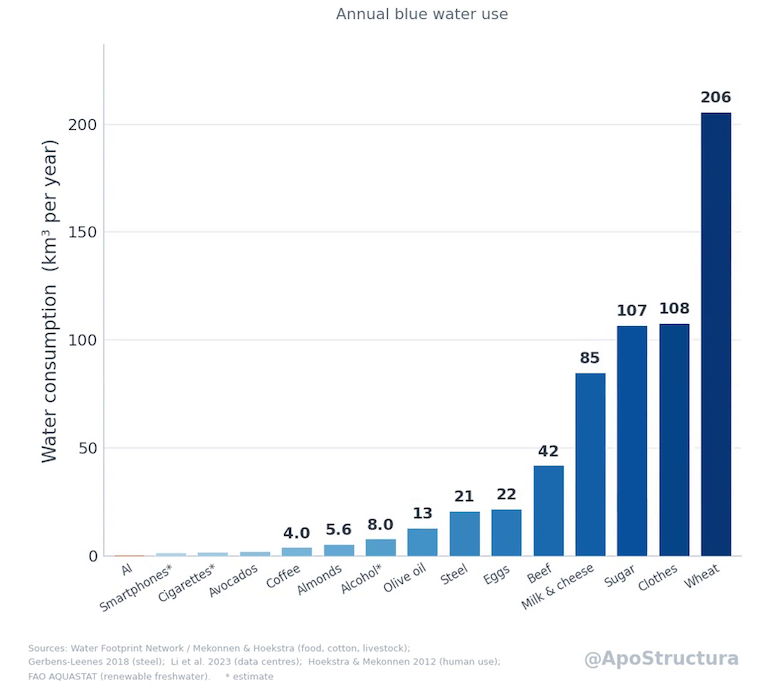
At the same time, the typical objections to AI in general are stats that are blown way out of proportion, like their water use:
Or maybe how big of an issue the power use actually is, let's say compared to the power use of the median household, even assuming that a person does 1000 queries per day (albeit the newer models can be more power intensive, though data center cards will still have better efficiency than anything self-hosted):
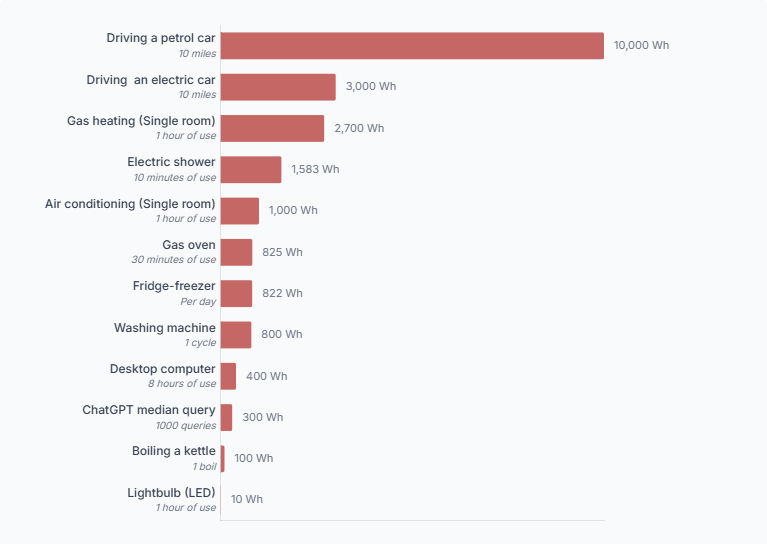
I might spend similar amounts of power (within the same order of magnitude, at least) heating up water for tea and coffee as I do with my agentic development.
And yet, instead of fixing the issues of zoning and the concentration of data centers in areas where water availability is limited in a local sense, or where the residential power grid will see increased load which, to be honest, is really stupid on the part of the people building the data centers - you are making literally everyone hate you because of you trying to do things on the cheap, instead of correctly.
The public sentiment seems to be geared towards just outlawing whatever they can and generating as much outrage as possible. In other words, people love simple explanations and being pointed at what to hate, instead of addressing the real causes, which might be harder to do.
But I digress, people focusing on the entirely wrong things is a rant for another time.
And yet, nobody is trying to force the AI companies to actually provide good and consistent service. In a sane world, if my ISP consistently throttles my connection for no good reason, below what I pay for and what has been agreed upon, I should have recourse. All of this AI stuff should be no different.
There's Anthropic with their misleading marketing and pretty much all of the big orgs with their trigger happy banning of users, alongside controlling what you can and cannot do with their services even when legal (e.g. Anthropic's killing of REA), alongside not being able to talk with actual support and constant messing around both with the token and usage limits that you get, as well as nerfing the models behind the scenes.
I absolutely believe that it should be regulated, the same way how it should be illegal for GMail to just cut your service (especially if on a paid tier) without a governmentally enforced mechanism of appeals and/or data export and migration to another provider, including but not limited to any accounts that you used to log in to other platforms with. Similarly, if AI services fail to sustain some TQA (let's say Token Quality Agreement, similar to your typical SLA), in that case they should at least be obligated to tell me: "We are currently throttling the reasoning effort of Claude due to limited compute. You will be charged at 0.75x the regular rate to make up for this decrease in quality." so I at least know to use another model during that time if I need quality.
But instead of that world, I just have Claude that sometimes gets really stupid. What's more, when you think about it, there's literally nothing preventing Anthropic from banning anyone who's outspoken against them - they can just claim some internal review or made up reason and axe their service for the coming decades, not less bad than losing access to an e-mail account you use for things. Before you say that it's a bit contrived, it also doesn't even have to be anything intentional, but rather some automated check that doesn't like any arbitrary detail anything you're doing.
While AI can be a huge force multiplier, you are more or less at the whims of the frontier orgs and that's that. Fun times.
Either way, I have a migraine (brought on by having to patch a llama.cpp setup on a non-standard topo overnight to use GPUs better, as well as getting treated like dirt by sysadmins for some reason), so you'll have to forgive my bluntness and lack of nuance. Here's hoping that future will bring something better than this.